What it's for
- Every hosted LLM you have used: continuous batching is why one GPU can serve many conversations at once without pausing between them.
- It is the other half of serving economics — the KV cache (step 2 of this path) bounds memory; the scheduler bounds idle time.
Good to know
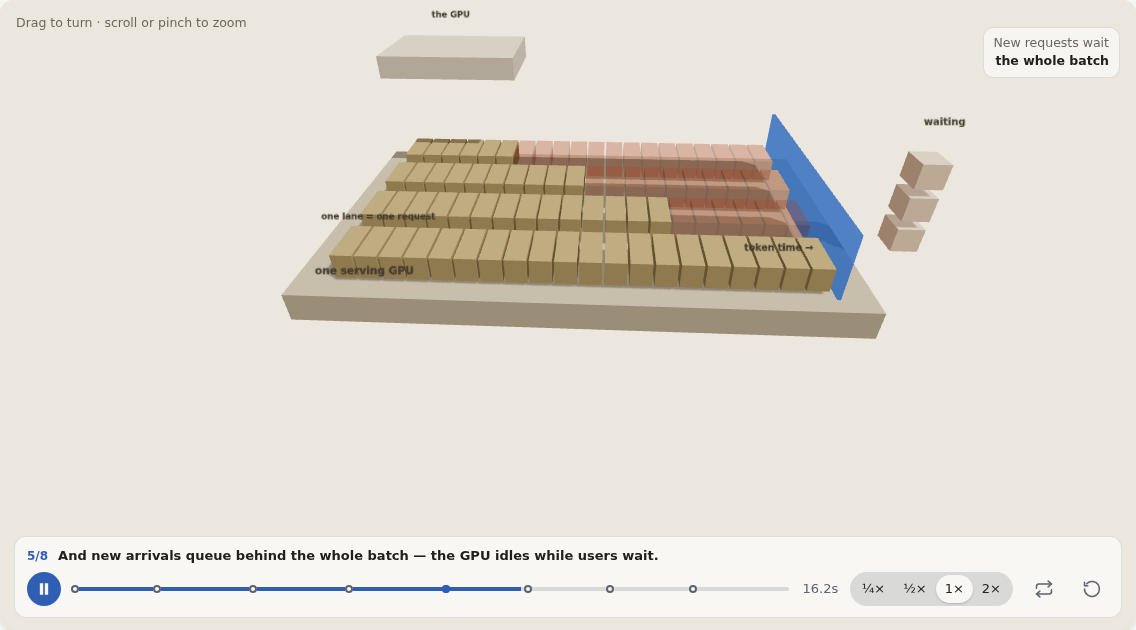
Token time runs left to right; each filled cell is one generated token. Real systems schedule a mixed batch of prefills and decodes every iteration, and the exact utilization depends on traffic and memory — the mechanism, not the percentages, is the point.
How it works, step by step
Why the steps go in this order
- Batches exist because a GPU is fastest on wide work: many sequences share one weight read per token.
- A static batch is all-or-nothing, so its finish time is its slowest member's — every shorter sequence's lane goes idle, and every new arrival waits behind them all.
- Scheduling after every single token removes the lockstep: a finished sequence leaves, a waiting one joins, and no lane ever sits empty.
- Idle time is the bill: filling it is what turns the same GPU into markedly more served tokens — in this scenario, about 1.6×.
Before you rely on it
Four lanes stand in for hundreds of concurrent sequences, token lengths are simplified, and the idle percentages are illustrative — real numbers depend on traffic, memory limits and prefill mix. The lockstep wait of static batching and the refill-on-finish of continuous batching are exactly as shown.