What it's for
- Training and running transformers, where attention's N×N score matrix is the memory bottleneck.
- It's a big part of why long contexts are affordable at all.
Good to know
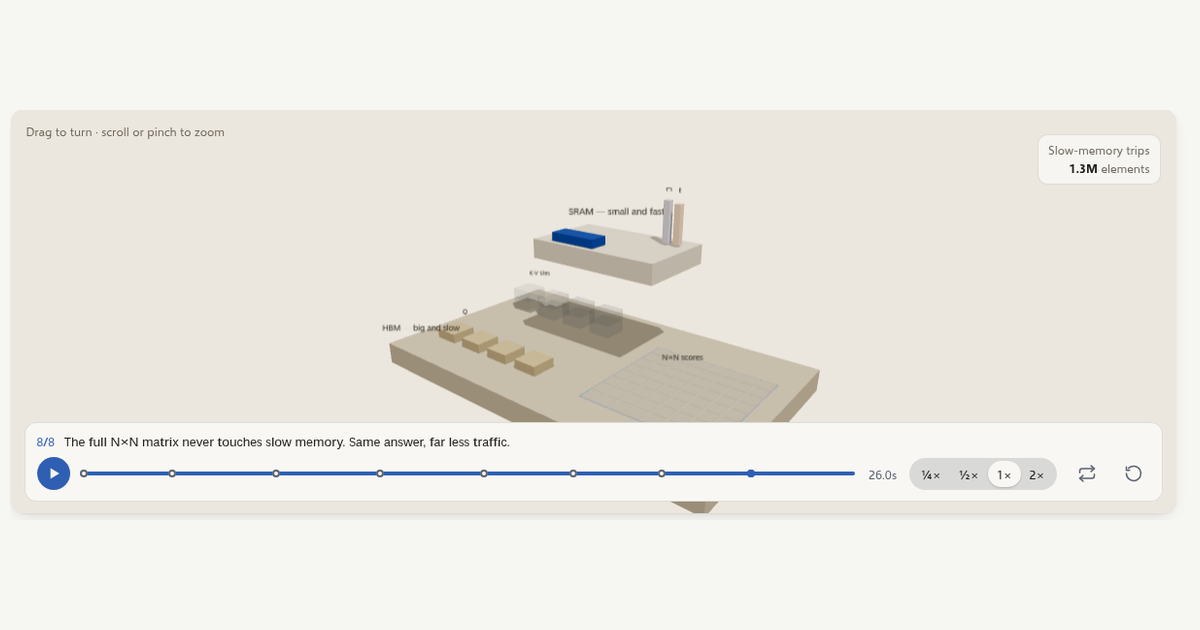
Same math, same output (up to float rounding). FlashAttention is an IO optimization, not an approximation.
How it works, step by step
Before you rely on it
Tile counts and traffic numbers come from a small illustrative model, not measured on a GPU. The shape of the win is real; the exact ratio depends on hardware, head dim and block sizes.